Physical Address
304 North Cardinal St.
Dorchester Center, MA 02124
Physical Address
304 North Cardinal St.
Dorchester Center, MA 02124
Compare the Apple Mac Studio and custom RTX workstations for running local LLMs in 2026. Discover specs, pricing, and the best hardware for your AI needs.
The ability to run Large Language Models (LLMs) locally is no longer a distant dream but a rapidly expanding reality. As AI models grow more sophisticated, the demand for powerful, accessible hardware capable of handling them offline surges. This shift offers unparalleled privacy, control, and speed for developers, researchers, and enthusiasts alike. However, choosing the right hardware can be a daunting task. Two prominent contenders have emerged in the consumer and prosumer space: Apple’s Mac Studio and custom-built RTX-powered workstations.
In 2026, these platforms represent distinct philosophies and technical approaches to local LLM execution. The Mac Studio, with its unified memory architecture and Apple Silicon prowess, offers an integrated, streamlined experience. Conversely, custom RTX workstations, leveraging NVIDIA’s industry-leading GPUs, promise raw power and extensive customization for the most demanding AI workloads. This article dives deep into a head-to-head comparison, dissecting their strengths, weaknesses, and suitability for running local LLMs today.
Understanding these differences is crucial for making an informed investment. Whether you’re fine-tuning a model, experimenting with AI agents, or simply running inference on your desktop, the hardware you choose will significantly impact performance, efficiency, and cost. We’ll explore the latest specifications, pricing, and the practical implications for running cutting-edge LLMs in 2026.
| Feature | Apple Mac Studio (2026 Models) | Custom RTX Workstation (2026 Build) |
| :———————- | :————————————————————— | :———————————————————————— |
| **Primary Strength** | Unified memory efficiency, ease of use, quiet operation, ecosystem integration | Raw GPU compute power, scalability, upgradeability, broad software compatibility |
| **GPU Focus** | Integrated Apple Silicon GPU (performance varies by M-series chip) | NVIDIA RTX GPUs (e.g., RTX 4090 Ti, RTX 5090, professional Quadro/RTX Ada) |
| **Max VRAM (Typical)** | Up to 192GB unified memory (shared with CPU) | Up to 48GB GDDR6X per GPU (multiple GPUs possible, e.g., 2x 48GB = 96GB) |
| **CPU Performance** | Excellent, high-core count Apple Silicon CPUs | Excellent, high-end Intel or AMD Ryzen CPUs |
| **Memory Bandwidth** | Extremely high (unified memory architecture) | High, but often lower than Mac Studio’s unified memory for GPU access |
| **Software Support** | Growing, optimized for macOS, Metal Performance Shaders (MPS) | Mature, extensive CUDA support, direct framework access (PyTorch, TensorFlow) |
| **Power Consumption** | Generally lower and more efficient | Can be significantly higher, especially under heavy GPU load |
| **Noise Levels** | Very quiet, even under load | Can be loud, depending on cooling solution and fan speeds |
| **Build & Form Factor** | Compact, premium all-in-one desktop | Highly customizable, can be larger tower PCs, requires assembly/vendor |
| **Price Range (Mid-High)**| $3,500 – $8,000+ | $4,000 – $10,000+ (highly variable based on components) |
| **Ease of Setup** | Very High | Moderate to High (depending on pre-built vs. DIY) |
| **LLM Performance** | Good for many tasks, excels with models fitting within unified memory | Excellent, especially for large models requiring high VRAM and parallel compute |
In 2026, the landscape for running LLMs locally is dominated by hardware choices that balance performance, memory capacity, and cost. Apple’s Mac Studio and custom-built RTX workstations represent the pinnacle of what’s accessible to power users outside of enterprise-grade server farms.
Apple’s Mac Studio has carved out a significant niche for creative professionals and developers, and its capabilities extend impressively into the realm of local LLMs. The key differentiator is Apple Silicon’s unified memory architecture. This design allows the CPU and GPU to access the same memory pool directly, drastically reducing data transfer latency and increasing effective memory bandwidth. This is particularly beneficial for LLMs, which are memory-intensive.
As of late 2026, the top-tier Mac Studio configurations feature the M4 Ultra chip, boasting up to 128 CPU cores and a 64-core GPU. Crucially, these systems can be configured with up to 192GB of unified memory. While this memory is shared between the CPU and GPU, it means a 192GB Mac Studio can effectively run models that might require 192GB of VRAM on traditional discrete GPU setups, though the raw parallel processing power of dedicated GPUs is different.
The Mac Studio’s strength lies in its efficiency, quiet operation, and seamless integration within the macOS ecosystem. Software support for running LLMs on Apple Silicon has matured considerably. Frameworks like PyTorch and TensorFlow offer Metal Performance Shaders (MPS) backend support, allowing models to leverage the GPU. Libraries such as Llama.cpp, MLX, and others are increasingly optimized for Apple Silicon, enabling efficient inference and even fine-tuning of many popular open-source models like Llama 3 variants, Mistral Large, and smaller custom models.
Pricing for a high-end Mac Studio configured for demanding tasks, such as the M4 Ultra with 192GB unified memory, 2TB SSD, and the full M4 Ultra chip, can range from approximately $7,000 to $8,500. While this is a substantial investment, it’s important to consider that this price includes a complete, high-performance desktop system with a premium build, display connectivity, and a refined user experience.
For users prioritizing ease of use, energy efficiency, and a quiet workspace, and whose LLM needs can be met within the unified memory constraints (e.g., models up to 70B parameters quantized), the Mac Studio is an exceptionally compelling option. Its integrated nature simplifies the setup and maintenance compared to a custom build.
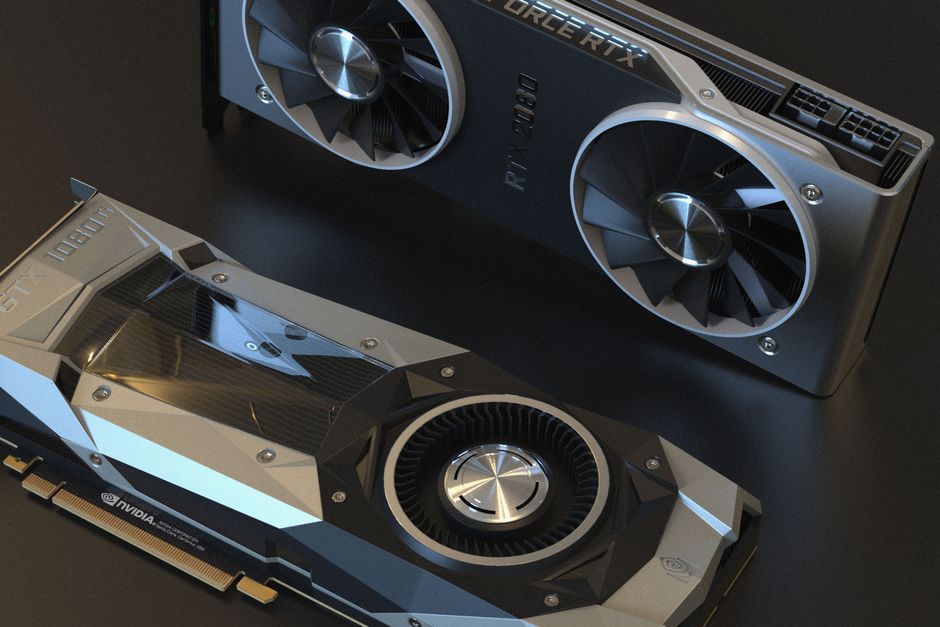
The custom RTX workstation represents the traditional powerhouse for AI and machine learning. Built around NVIDIA’s cutting-edge GeForce RTX and professional RTX Ada Generation GPUs, these machines offer unparalleled raw compute power and memory capacity for LLM tasks. As of late 2026, the pinnacle for consumer-grade LLM acceleration is often the NVIDIA RTX 4090 Ti or its successor, the rumored RTX 5090, each typically offering 24GB of GDDR6X VRAM.
The true advantage of an RTX workstation lies in scalability and VRAM potential. A single high-end RTX card provides 24GB of VRAM. However, users can build systems with multiple GPUs â for instance, a dual RTX 4090 Ti setup offers 48GB of dedicated VRAM, and more enthusiast builds might even accommodate three or four cards, pushing VRAM capacity significantly higher, albeit with complexities in power delivery, cooling, and software configuration (e.g., model parallelism).
NVIDIA’s CUDA ecosystem remains the de facto standard for GPU-accelerated computing, especially in AI. Virtually all major AI frameworks and libraries (PyTorch, TensorFlow, JAX) are built with CUDA support as a primary target. This means compatibility and performance optimization for LLMs are generally superior and more mature on NVIDIA hardware. Running large models, especially those exceeding 70B parameters even when quantized, often necessitates the high VRAM capacity that multiple RTX GPUs can provide.
The cost of a custom RTX workstation is highly variable. A robust build featuring a top-tier CPU (like an Intel Core i9-14900K or AMD Ryzen 9 7950X3D), 64GB of DDR5 RAM, a powerful PSU, and a single RTX 4090 Ti (24GB VRAM) could start around $4,000. Adding a second RTX 4090 Ti would easily push the price to $6,500-$7,500, not including peripherals or professional GPUs which can double the cost per card.
The primary strengths of RTX workstations are their raw performance, extensive VRAM potential through multi-GPU configurations, and the maturity of the NVIDIA software stack. They offer greater flexibility for users who need to push the boundaries of model size and complexity, and who are comfortable with the nuances of PC building and driver management. However, they typically consume more power, generate more heat, and can be significantly louder than a Mac Studio.
When it comes to running LLMs, several factors dictate performance: VRAM capacity, memory bandwidth, raw compute (FLOPS), and software optimization. For inference (running pre-trained models), VRAM capacity is often the primary bottleneck. A model must fit entirely within the GPU’s VRAM (or unified memory) for optimal speed. Larger models, such as 70B parameter models (like Llama 3 70B) or even larger ones, require significant VRAM. Quantization techniques (reducing the precision of model weights) can significantly reduce VRAM requirements, making larger models feasible on less VRAM.
For a 70B parameter model, even heavily quantized (e.g., 4-bit quantization), you might need around 40-50GB of VRAM for comfortable inference. This means a single RTX 4090 Ti (24GB) is insufficient on its own, while a Mac Studio with 192GB unified memory can handle it easily. However, for smaller models (e.g., 7B or 13B parameters) or heavily quantized larger models, a single RTX 4090 Ti will likely outperform the Mac Studio’s GPU due to its sheer number of CUDA cores and higher clock speeds.
Training and fine-tuning LLMs are even more VRAM-hungry, often requiring multiples of the VRAM needed for inference. This is where multi-GPU RTX workstations truly shine, offering the potential for significantly more dedicated VRAM than a Mac Studio can provide, albeit at a higher cost and complexity. The raw compute power of multiple high-end NVIDIA GPUs also accelerates training times.
The unified memory of the Mac Studio offers excellent bandwidth, which is crucial for LLMs that frequently access weights and activations. However, the parallel processing capabilities of multiple dedicated RTX GPUs, especially for tasks that can be heavily parallelized, can still offer superior throughput. The choice heavily depends on the specific LLM, the task (inference vs. training), and the available budget for memory and compute.
Selecting the best local LLM hardware kit in 2026 hinges on your specific needs, budget, and technical comfort level. Hereâs a breakdown to guide your decision:
1. Define Your Use Case:
2. Assess Your Budget:
3. Consider Software Ecosystem and Ease of Use:
4. Memory vs. Compute:
5. Future-Proofing and Upgradeability:
Q1: Can I run large LLMs like Llama 3 70B locally on these machines?
A1: Yes, but with caveats. On a Mac Studio with 192GB unified memory, you can run quantized versions of Llama 3 70B and even some unquantized versions if memory allows. On a custom RTX workstation, you would need at least two high-end GPUs (e.g., 2x RTX 4090 Ti) to achieve the necessary 48GB+ of VRAM for efficient operation of such models.
Q2: Which platform is better for fine-tuning LLMs?
A2: Custom RTX workstations generally offer superior performance and scalability for fine-tuning. The ability to install multiple high-VRAM NVIDIA GPUs provides more dedicated memory and raw compute power, crucial for the iterative nature of fine-tuning. Mac Studio can fine-tune smaller models or perform limited fine-tuning on larger ones, but it’s not its primary strength compared to multi-GPU RTX setups.
Q3: Is Apple Silicon (Mac Studio) optimized for AI workloads?
A3: Apple Silicon is increasingly optimized for AI and machine learning tasks, especially those that benefit from its unified memory architecture and high memory bandwidth. Frameworks and libraries are adding Metal Performance Shaders (MPS) support, and dedicated AI cores on Apple chips are improving performance. However, it still lags behind NVIDIA’s mature CUDA ecosystem in terms of raw, scalable compute power for the most demanding tasks.
Q4: How much VRAM do I really need for local LLMs in 2026?
A4: This varies greatly. For inference of smaller models (7B-13B parameters) or heavily quantized larger models, 12GB-24GB might suffice. For running 70B models with moderate quantization, 40GB-64GB is ideal. For larger models or fine-tuning, 80GB or more is often recommended, which typically requires multi-GPU setups or high-end Mac Studio configurations.
Choosing between the Apple Mac Studio and a custom RTX workstation for local LLM hardware in 2026 depends entirely on your priorities and technical needs. There isn’t a single “winner” for everyone.
For the user who prioritizes ease of use, system integration, energy efficiency, and a quiet operating environment, the Apple Mac Studio is the clear choice. Its unified memory architecture, especially in configurations with 128GB or 192GB, provides ample capacity for many common LLM inference tasks, including large quantized models. It offers a powerful, plug-and-play experience for macOS users who want to experiment with local AI without the complexities of building and managing a high-performance PC.
However, for the user demanding maximum raw compute power, the greatest VRAM capacity through multi-GPU configurations, and the most mature software ecosystem for AI development, the custom RTX workstation is superior. NVIDIA’s CUDA platform remains the industry standard, and the ability to scale up to multiple RTX 4090 Ti or RTX 5090 cards offers performance and memory ceiling that the Mac Studio cannot match. This is the platform for serious researchers, developers pushing the boundaries of model size, or those focused on efficient fine-tuning and training.
Our Recommendation: If you are an individual user or small business owner focused on running LLMs for inference, content generation, or integration into existing macOS workflows, and VRAM needs are met by 192GB, opt for the Mac Studio (M4 Ultra, 192GB unified memory). If your work involves extensive model training, fine-tuning, or running the absolute largest, state-of-the-art models that exceed 192GB capacity even with quantization, a custom-built dual or triple RTX workstation is the more powerful, albeit more complex and potentially expensive, path forward.
Prices and features mentioned are accurate as of the date of publication. Always check the official provider website for the most current pricing and availability.